Decision in 60 seconds
A January SERP capture can accurately document January and still be unsafe for a July investment decision after a product launch, algorithm change or market-entry event. Source reputation does not prevent evidence decay.
Evidence Freshness and Reliability Standard
Decide what a specific evidence record may support now.
- Decision question
- Can this record support this exact claim, context and decision?
- Governing rule
- A source name or timestamp is never enough. Test provenance, age, directness, reproducibility, context fit and decay risk together.
- Governed output
- Current, Degraded, Stale or Unresolved—with a permitted use and reopen trigger.
- Boundary
- This standard governs evidence fitness. It does not prove causality, forecast rankings or validate commercial outcomes.
Use evidence only when its provenance, observation date, directness, reproducibility, context fit and review window are explicit enough for the decision. Otherwise qualify the wording, refresh the record or hold the claim.
Before an investment decision
Can a January competitor ranking report support July budget allocation?
Evidence: competitor ranking report collected in January.
Decision: whether to fund a six-month content programme in July.
| Control | Result | Decision implication |
|---|---|---|
| Provenance | Pass | The source and January collection date are known. |
| Observation age | Outside window | The evidence is older than the declared budget-review window. |
| Context fit | Changed | The competitor launched new pages and the SERP set changed after collection. |
| Decay risk | High | A material investment could be based on an opportunity that no longer exists. |
The January report may remain useful as historical context, but it cannot be the sole basis for July budget allocation.
Use the tool
30-second evidence fitness checker
Compare the record’s age with its declared review window, then test whether a material event, context mismatch or contradiction makes the record unsafe. The checker runs locally in the browser and sends no data.
A timestamp does not make evidence current.
How it works
The evidence fitness gate
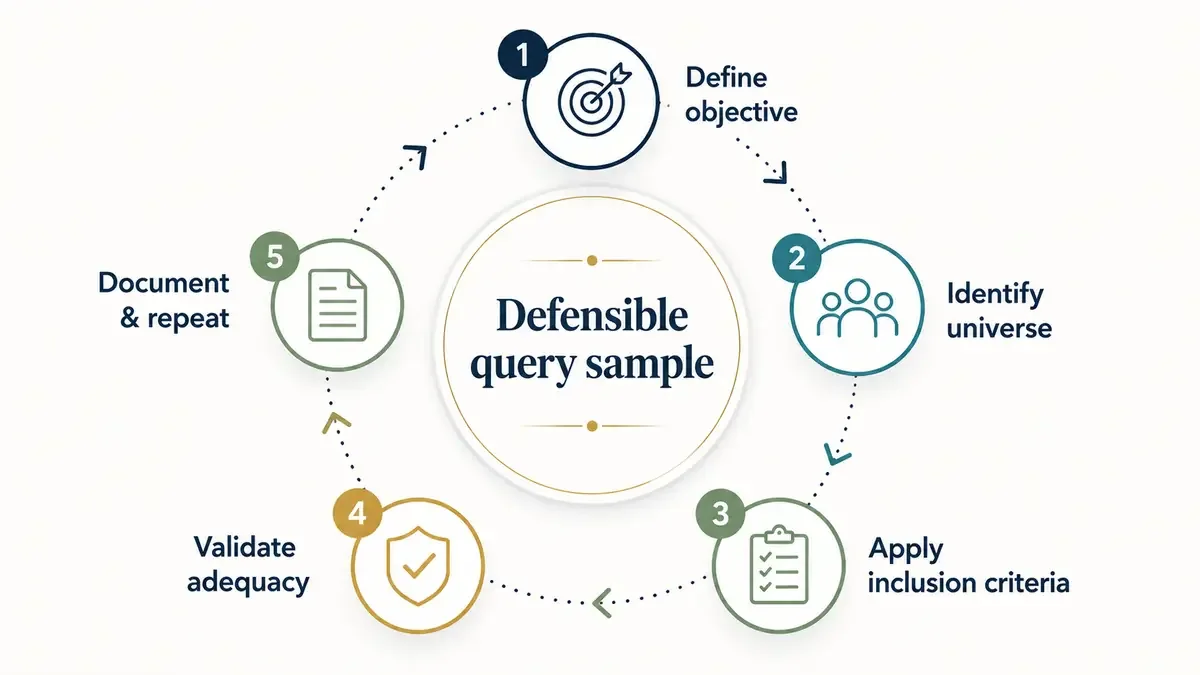
The standard uses one primary semantic model. Each material record moves through six controls before a governed state and permitted wording are assigned.
Evidence record → six controls → governed use
- Provenance
Name who produced or observed the evidence and when the underlying observation was collected.
- Observation age
Measure age from the observation—not the publication, upload or republishing date.
- Directness
Distinguish direct observation from inference, synthesis and derivative estimates.
- Reproducibility
Confirm another reviewer can inspect the record or repeat the method.
- Context fit
Match buyer, offer, geography, device, language, market and decision stage.
- Decay risk
Set a review window and event trigger based on volatility and decision consequence.
Inside the review window, context-matched and not superseded.
Still informative, but wording or decision use must narrow.
The review window expired or a material event invalidated current use.
Required evidence is missing or material contradictions remain unbounded.
| Control | Question | Required record |
|---|---|---|
| Provenance | Who produced or directly observed the information? | Named origin, source class and collection date. |
| Observation age | How long ago was the underlying condition observed? | Verifiable age and declared review window. |
| Directness | Does the record observe the claim or repeat another interpretation? | Direct, inferred or derivative classification. |
| Reproducibility | Can another reviewer inspect or rebuild the finding? | Evidence copy, method and replay note. |
| Context fit | Does the record match the buyer, market and decision? | Explicit fit and excluded contexts. |
| Decay risk | What change would make the record unsafe? | Review date, event trigger and accountable owner. |
Messy reality
Three sources disagree and the budget decision cannot wait
This composite failure pattern shows why the framework must separate the claim being made from the reputation or recency of each source.
Direct and current for advertised packaging.
Direct qualitative evidence, but sampled and incentive-sensitive.
Derivative and stale for current pricing.
Controlled decision
Current: the public page can support a claim about advertised list pricing. Degraded: the sales interview can support a qualified statement that negotiated terms may differ. Stale: the cached historical price cannot support current pricing. Unresolved: actual realised deal terms remain unknown.
Pause any claim about realised deal terms or market-wide pricing.
Request permissioned contract, invoice or customer evidence matched to the target segment.
Escalate when the budget decision depends on the unresolved price difference.
Stop the claim when no direct evidence can be obtained and the distinction is material.
Reopen when pricing changes, a stronger record appears or the decision scope changes.
Founder design observation: when records disagree, the defensible output is often a narrower claim—not a forced winner.
How it is operated
Workflow, failure modes and decision boundaries
The default path stays compact. Open the advanced controls only when the decision is material, reviewers disagree or the evidence state is challenged.
Advanced six-stage workflow
- RecordCapture source, observed value, date, method and market context.
- ClassifyIdentify source class, directness and independence.
- TestCheck reproducibility, contradiction and context fit.
- Set decayAssign a review window and event trigger.
- Govern useLimit the claim to the decision the record can support.
- Refresh or retireUpdate, downgrade, supersede or preserve as history.
Common failure modes
The article date is mistaken for the observation date.
A single SERP or pricing capture is treated as a stable market condition.
A recent page repeats an older estimate without adding evidence.
No review point is assigned to a fast-changing claim.
A respected provider name replaces claim-level inspection.
Uncertainty is averaged into a score instead of being recorded separately.
Use, limits and stop condition
Use the standard whenever competitor evidence, SERP observations, tool estimates or first-party records influence classification, prioritisation or executive recommendations.
Do not use it as a universal provider score, automatic recommendation, causal test or performance forecast.
Pause when the accountable decision, material exclusions or minimum evidence requirement cannot be stated without contradiction.
Keep confidence separate from the evidence state. Confidence describes how secure the classification is; it does not change Stale evidence into Current evidence.
How it is governed
Validation status and claim-level evidence record
Published deterministic logic
- Six evidence controls and four governed states
- Deterministic browser checker with no network request
- Current-live article and asset capture with zero source writes
- Explicit claim boundaries and reopen rules
Independent reviewer reliability
Status: NOT RUN. A future gate requires blind reviewers, raw agreement and a suitable chance-corrected reliability measure.
Outcome and adoption evidence
Status: NO_DATA. No independent adoption, ranking, lead, revenue or causal outcome study is claimed.
Claim-level freshness record from the five-page governance audit
The record below uses the read-only SERPIFAI evidence-governance audit completed on 5 July 2026 at 17:09:17Z. It is a first-party process record. It does not establish ranking improvement, demand, leads, revenue or causal impact.
| Claim | Observed at | Freshness window | State | Permitted use and reopen trigger |
|---|---|---|---|---|
| Five exact current HTML baselines were frozen and website files modified equalled zero. | 2026-07-05T17:09:17Z; Batch 05 report manifest. | Valid for 30 days or until any target file hash changes. | Current | Supports a no-write audit claim only. Reopen when a target hash changes. |
| Twenty-two requirements were machine-undetected. | 2026-07-05T17:09:17Z; evidence-gap matrix. | Valid only until content or detector rules change. | Current | Prioritises editorial work. It cannot certify substantive quality. |
| The diagnostic cluster score was 8.7/10. | 2026-07-05T17:09:17Z; scoring model v1.0.0. | Valid only under the same model and five-route scope. | Degraded if the scoring logic, sample or route set changes. | Allows like-for-like diagnostic comparison, not an external authority claim. |
| Search visibility, lead quality, revenue and attribution outcomes. | No outcome observation was collected. | No expiry window can be assigned to absent evidence. | Unresolved | Do not infer an outcome. Reopen after a defined baseline and observation window exist. |
This framework can govern whether an evidence record is fit for a stated decision. It does not certify source-provider accuracy, predict search performance, establish causality or prove commercial return.
Evidence system boundary
Where this framework hands off
Reviewer prompts
Questions reviewers should answer
Is recent evidence automatically reliable?
No. A recent record can still be derivative, irreproducible or context-mismatched. Freshness is one control inside evidence fitness.
Can older evidence remain usable?
Yes, when the underlying condition is stable, the context still matches, no superseding event has occurred and the record remains reproducible. The permitted wording must remain inside that boundary.
What happens when reviewers disagree?
Preserve both classifications and rationales, compare the exact claim and scope boundary, request the missing evidence and keep the state Unresolved until the conflict is bounded.
What should trigger reassessment?
A source correction, pricing or product change, new market entry, algorithm change, repeated anomalous observations, a stronger contradictory source, an expired review window or a changed decision context.
Freshness × Change × Consequence
How to read it: select a checkpoint to isolate that part of the method. The canvas shows the relationship; the inspector explains what the checkpoint changes in the decision.
Sources and boundaries
Evidence and method notes
W3C PROV-O provides a vocabulary for provenance records, while the UK AQuA Book frames analytical quality around robust, fit-for-purpose methods. Google Search Central provides context for helpful, reliable content and Article structured data. These sources inform the method; they do not certify the proprietary framework.
- W3C PROV-O provenance ontology
- UK Government AQuA Book
- Google Search Central — helpful, reliable, people-first content
- Google Search Central — Article structured data
Status: Founder reviewed by Pero Baldjiev. Founder reviewed by Pero Baldjiev.